
Think together · Start with a story
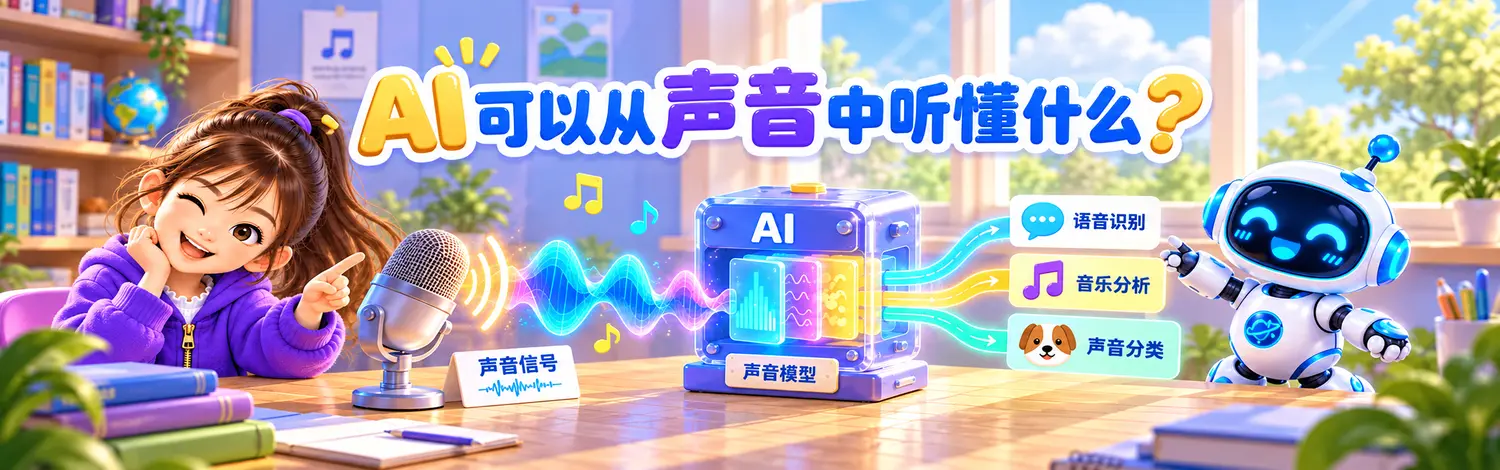
A girl claps, speaks, and rings a bell. The robot receives sound each time, but the task is different.
Break down the process
- SamplingSound becomes numbers
- Features or representationKeep changes over time
- Model taskRecognize speech or sound types
- OutputText, labels, and more
Sound models process audio signals that change over time.
Recognizing spoken words, identifying a sound, and distinguishing a musical rhythm are different tasks. A model may use information such as frequency and timing, but it cannot directly read everything a speaker intends.
Noise, accents, and recording quality can affect the result.
Your turn to try
If wind covers part of a sentence in a recording, should the model invent a definite transcript?
Ready? Open to see the explanation
No. It can mark the unclear part and ask a person to check, instead of treating a guess as a record.
One idea to remember
Sound models process audio signals that change over time.
Try covering the picture above and explaining each step to your family. If one step is hard to explain, revisit that card.