
Think together · Start with a story
A girl gives a robot a photo and asks, “Which cup is on the left?” The model needs to handle different kinds of information at the same time.
Break down the process
- ImageProvides visual content
- TextExplains the question
- CombineConnects both representations
- OutputProvides an answer
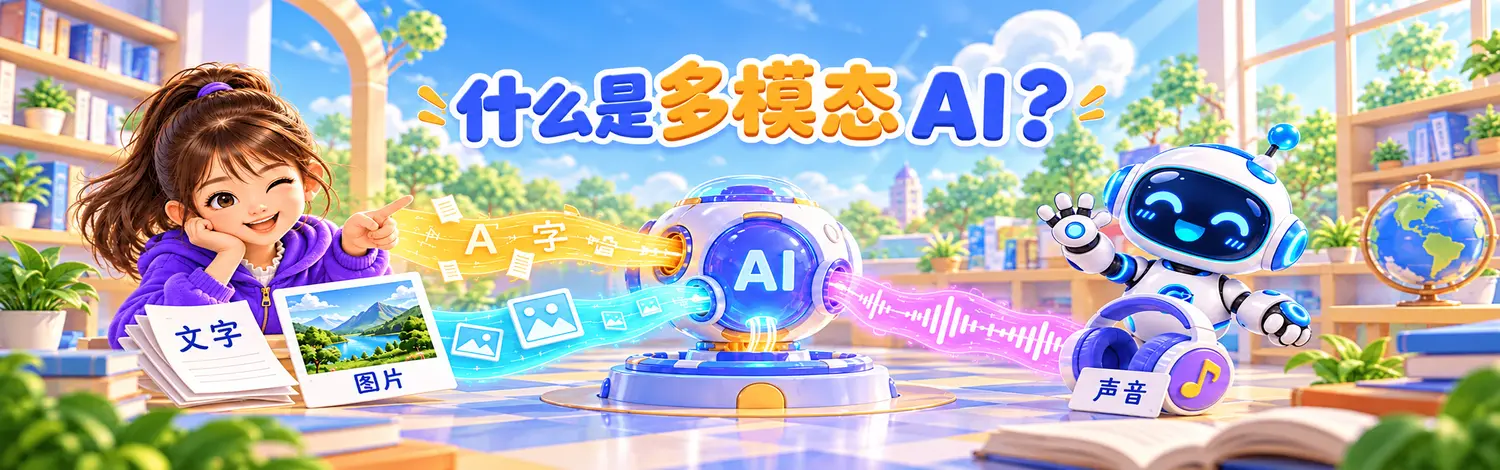
Multimodal AI processes or connects different kinds of data, such as text, images, and sound.
Think of a “modality” as a form of information. An image shows the scene, while text says what to look for. Combining them can help complete a task.
Which inputs and outputs a system supports depends on its design. Calling something multimodal does not mean it can do everything.
Your turn to try
If you give a model a blurry photo and ask it to read a tiny house number, should it simply guess?
Ready? Open to see the explanation
No. It should say that the number is unclear and ask for a clearer, non-sensitive image or suggest another way to check.
One idea to remember
Multimodal AI processes or connects different kinds of data, such as text, images, and sound.
Try covering the picture above and explaining each step to your family. If one step is hard to explain, revisit that card.